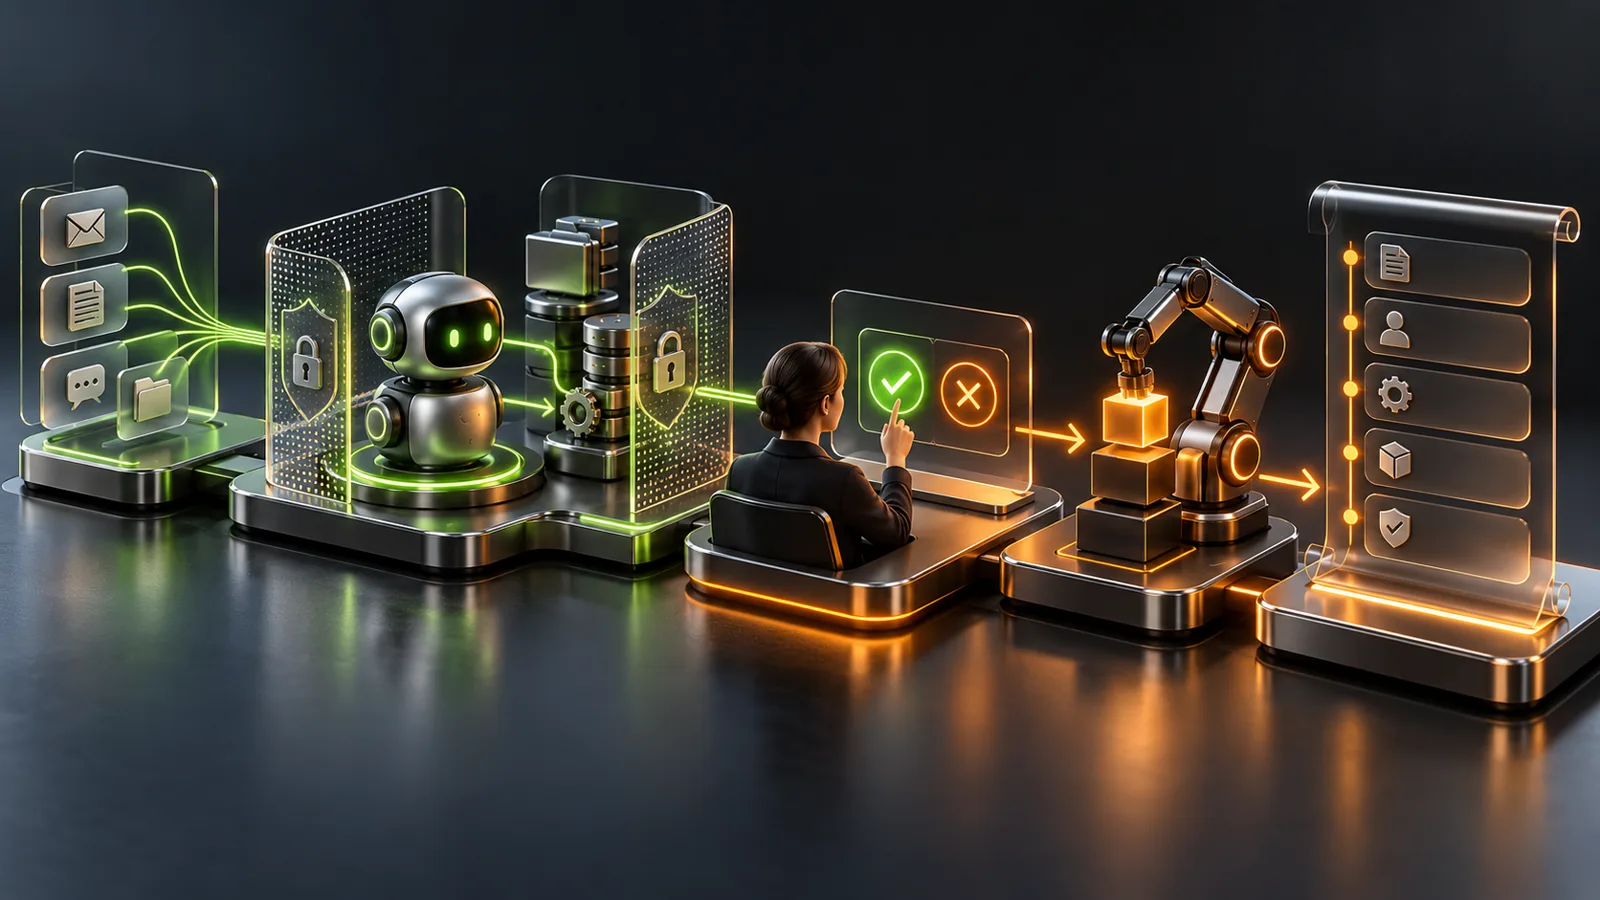
How to Add Human Approval and Guardrails to an AI Agent
Keep people in control of consequential agent actions.
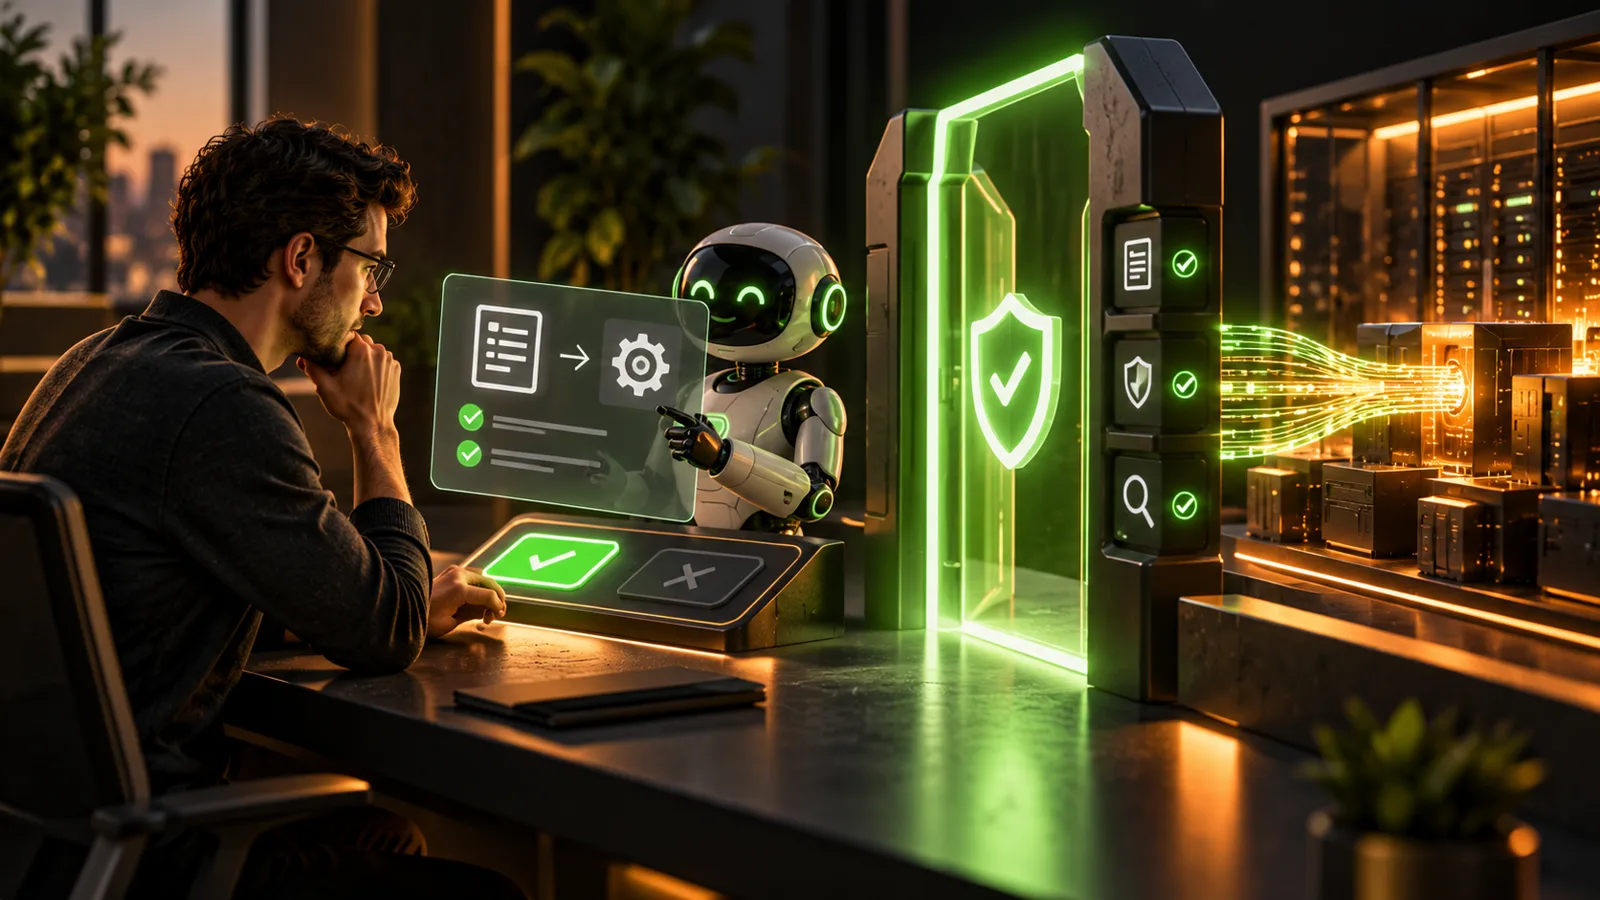
Artificial intelligence is evolving rapidly from read-only chatbots to read-write agents. Today, builders are deploying autonomous systems that can read emails, query databases, draft proposals, and even execute financial transactions. However, this shift from conversational AI to agentic workflows introduces a massive new risk: allowing a hallucinating or manipulated language model to take irreversible actions on your behalf.
Learning exactly how to add human approval and guardrails to an AI agent is a non-negotiable skill for anyone building reliable, production-facing AI products. Without these critical safety mechanisms, a simple prompt injection or logic error could result in deleted records, inappropriate customer communications, or uncontrolled financial spending.
At VibeCode Academy, we believe in building AI tools that actually work in the real world. That means acknowledging that AI models make mistakes. To build trust with your users and stakeholders, you must keep people in control of consequential agent actions. This comprehensive guide will walk you through the core concepts of agent safety, including approval thresholds, the principle of least privilege, audit trails, failure modes, and escalations. By the end of this article, you will have a clear, step-by-step roadmap for implementing robust human-in-the-loop (HITL) workflows.
Guardrails vs. Human Approval in AI: Understanding the Difference
Before diving into implementation, it is vital to distinguish between guardrails and human approvals. While they serve the same overarching goal—keeping your AI agent safe—they operate quite differently.
Guardrails are automated, hard-coded boundaries placed around an agent. They do not require a human to intervene; they simply prevent the agent from taking unauthorized actions or generating specific types of output. Examples of automated guardrails include:
- Regular expressions that scrub personally identifiable information (PII) before it is sent to a language model.
- Code-level checks that prevent an agent from refunding a customer more than a hardcoded maximum amount (e.g., $50).
- Network-level restrictions that only allow the agent to make API calls to pre-approved domains, blocking attempts to reach out to malicious servers.
Human Approvals, often called Human-in-the-Loop (HITL), represent a deliberate pause in the agent's execution. When an agent decides it needs to take a high-stakes action—like sending a finalized contract to a client—it must stop, serialize its current state, and send a request to a human. The human reviews the proposed action and either approves it, rejects it, or provides feedback for the agent to modify its approach. Only after explicit human authorization does the agent proceed.
Technical Prerequisites for AI Agent Approval Workflows
Adding a human pause to an AI agent is not as simple as asking the language model to "wait for permission." Language model API calls are stateless and synchronous; they expect an immediate response. If your agent is waiting hours for a manager to approve an action, keeping an HTTP request open will result in a timeout. To implement proper approvals, you need an architecture capable of asynchronous execution.
- A Stateful Orchestration Layer: You must use a framework or workflow engine that supports pausing and resuming state. Modern agent frameworks like LangGraph, or workflow engines like Temporal and AWS Step Functions, allow you to save the agent's memory and current execution graph to a database. When the human responds, the framework wakes up the agent and injects the human's response into the state.
- A Notification and UI Channel: The human needs a way to receive the approval request and take action. This is commonly handled via enterprise messaging platforms like Slack or Microsoft Teams (using interactive buttons), email with unique authorization links, or a custom internal web dashboard built specifically for reviewing agent actions.
- Webhooks or API Callbacks: Your application must expose an endpoint capable of receiving the human's decision from the UI channel. This webhook will be responsible for validating the human's identity, updating the database, and triggering the orchestration layer to resume the agent's task.
Core Concepts for Safe AI Agent Design
Building a secure approval system requires adherence to several foundational engineering and security principles. Do not skip these concepts if you intend to deploy your agent in a commercial environment.
Approval Thresholds and Alert Fatigue
If you require a human to approve every single action an agent takes, you lose all the efficiency gains of automation. Worse, humans will develop "alert fatigue," mindlessly clicking "Approve" without actually reviewing the details. To combat this, you must define smart approval thresholds. For example, an agent might be allowed to autonomously send internal Slack summaries, but drafting an email to a client requires human review. Or, an agent might autonomously issue refunds under $20, but anything between $20 and $100 requires manager approval. Set your thresholds based on the actual business risk of the action.
The Principle of Least Privilege
An AI agent should only have access to the exact data and permissions it needs to perform its assigned task—nothing more. If your agent's job is to read customer support tickets and draft replies, it should not have an API key that allows it to delete user accounts in your production database. Always scope your API keys, database roles, and IAM permissions tightly. Even if an attacker successfully uses a prompt injection to bypass your approval layer, the principle of least privilege ensures the damage is strictly contained.
Immutable Audit Trails
When an agent takes a consequential action, you must have a perfect record of why that action occurred. An audit trail should log the original user prompt, the agent's chain of thought or intermediate reasoning, the exact payload of the proposed action, the identity of the human who approved it, and the timestamp. This log must be immutable (tamper-proof). If a customer complains about an incorrect refund six months later, you need to know exactly who approved it and based on what data.
Step-by-Step Implementation: Adding Human Approval to AI Agents
Let us break down the exact steps to build a human-in-the-loop workflow for your AI agent. While the code will vary depending on your tech stack, the architectural pattern remains the same.
Step 1: Define Consequential Tools
In modern agent architectures, agents interact with the world via "tools" or "functions." Begin by auditing your agent's toolbox. Categorize each tool as either "Safe" (e.g., searching Wikipedia, calculating a sum) or "Consequential" (e.g., executing a database query, sending an email, transferring funds). Mark the consequential tools in your codebase with a flag, such as requires_approval: true.
Step 2: Build the Interruption and Serialization Mechanism
When the agent's language model decides to invoke a tool marked as requires_approval, your application logic must intercept the call before it executes. Instead of running the tool, your system must serialize the agent's current state—including its conversation history, variables, and the specific parameters it wants to pass to the tool—and write this state to a persistent database. The agent's active process is then terminated or put to sleep.
Step 3: Route the Request to the Human Reviewer
Once the state is saved, trigger a notification to the designated human reviewer. This notification must provide complete context so the human can make an informed decision. For example, a Slack message should include:
- The Goal: "The user requested a refund for order #12345."
- The Proposed Action: "The agent intends to call the Stripe API to refund $45.00."
- The Agent's Reasoning: "The item arrived damaged, which qualifies for a full refund under policy section 3B."
- Action Buttons: "Approve", "Deny", and "Provide Feedback".
Step 4: Receive the Decision and Resume Execution
When the human clicks a button, a webhook payload is sent back to your server. Your server must verify the identity of the user clicking the button (e.g., validating the Slack signature or checking the session token on your web dashboard). Then, retrieve the agent's state from the database, append the human's decision as a new message in the context window (e.g., "Human approved the action" or "Human rejected the action with feedback: Please offer a $20 credit instead"), and restart the agent. The agent will read this new context and proceed accordingly.
A Practical Example: Building a Customer Refund AI Agent
To make this concrete, imagine you are an aspiring AI service provider building a "Customer Support Triage Agent" for an e-commerce brand. The agent has access to a Zendesk inbox and a Stripe API tool.
- The Scenario: A customer emails asking for a refund because their delivery was late. The agent reads the email, checks the shipping API, confirms the delay, and decides to issue a 50% refund.
- The Guardrail: You have hardcoded a rule in your execution environment that any refund over $50 is strictly blocked. The proposed refund is $30, so it passes the automated guardrail.
- The Approval: Because the action involves moving money, the
issue_refundtool is flagged for human approval. The agent pauses and sends a rich message to the #support-approvals Slack channel. A human support manager reviews the agent's reasoning, agrees with the assessment, and clicks "Approve." The webhook fires, the agent wakes up, executes the Stripe API call, and drafts a polite email to the customer confirming the refund.
Managing AI Failure Modes and Action Escalations
Building a demo of an approval workflow is easy, but making it production-ready requires handling the edge cases. What happens when things go wrong?
Handling Timeouts
Humans take vacations, sleep, and miss notifications. If an agent pauses for approval, it cannot wait forever. You must implement a timeout mechanism (e.g., a background cron job). If an action is not approved within 24 hours, the system should automatically cancel the pending action, log a timeout failure, and instruct the agent to inform the original user that the request expired.
Agent Misinterpretation
Sometimes, a human rejects an action and provides feedback, but the language model misinterprets the feedback and tries the same wrong action again. To prevent infinite loops of the agent repeatedly asking for the same approval, implement a retry limit. If an agent's proposed action is rejected three times in a row, the agent should automatically escalate the entire conversation to a human support queue and gracefully exit.
Escalation Policies
For urgent workflows, relying on a single human is dangerous. Build escalation paths. If Manager A does not approve or deny an urgent infrastructure deployment within 15 minutes, the webhook system should automatically route the approval request to Manager B, or alert an on-call pager system.
Production-Ready AI Test Checklist
Never claim a human-in-the-loop agent is production-ready without rigorously testing its security, failure handling, and ownership models. Use this checklist before deploying:
- State Security: Can a malicious user tamper with the serialized state in the database while it is waiting for approval? (Ensure database access is restricted and state is optionally cryptographically signed).
- Bypass Testing: Can prompt injection trick the agent into calling the API directly without invoking the approval tool? (Enforce permissions at the API layer, not just the LLM prompt level).
- Idempotency: If a human accidentally clicks the "Approve" button twice due to a slow network, will the webhook charge the customer twice? (Implement idempotency keys on your callback endpoints).
- Graceful Degradation: If your Slack integration or web dashboard goes down, does the agent fail safely and inform the user, or does it crash silently?
- Clear Ownership: Is it legally and operationally clear who owns the final action? The audit trail must definitively link the execution to the human who clicked "Approve."
Conclusion and Next Actions
Autonomous AI agents offer incredible leverage for businesses, but that leverage must be balanced with strict safety protocols. By implementing solid guardrails, setting intelligent approval thresholds, enforcing the principle of least privilege, and designing asynchronous pause-and-resume workflows, you can deploy agents that are both powerful and trustworthy.
Your next action should be to start small. Take a basic script you have written—perhaps one that drafts emails—and try to implement a pause mechanism using a lightweight framework or a simple database table. Build a small web server that receives a "Yes" or "No" parameter via a URL to resume the script. Once you master this fundamental loop, you can scale it to complex enterprise architectures.
If you want to move beyond tutorials and start shipping real, secure, and profitable AI tools, come join us at VibeCode Academy. We teach founders, builders, and aspiring AI service providers how to build, ship, and sell useful web products and AI agents with confidence.
Frequently Asked Questions (FAQ)
Can I just tell the agent in the system prompt to ask for permission?
No. While you can prompt an LLM to "ask the user before proceeding," relying on natural language for security is unsafe. Language models are easily distracted and can be bypassed via prompt injection. True human approval must be enforced at the code and infrastructure layer, intercepting the actual tool execution.
What is the best framework for building human-in-the-loop agents?
Currently, frameworks that treat agent execution as a state machine are best suited for this. LangGraph is very popular in the Python ecosystem for defining cyclical graphs with built-in pause capabilities. For enterprise-grade reliability across multiple languages, durable execution engines like Temporal are excellent choices.
How do I handle approvals for high-volume tasks?
For high-volume tasks, rely heavily on automated guardrails rather than manual approvals. Use explicit approvals only for outliers, edge cases, or actions that exceed strict financial thresholds. You can also implement "batch approvals," where a human reviews a dashboard of 50 queued agent actions and approves them in bulk.